


DocuMind
A multimodal RAG assistant for technical documents. Instead of pasting a whole PDF into a chatbot every time, it indexes the document once, retrieves only the evidence each question needs, and has an LLM answer from that evidence.
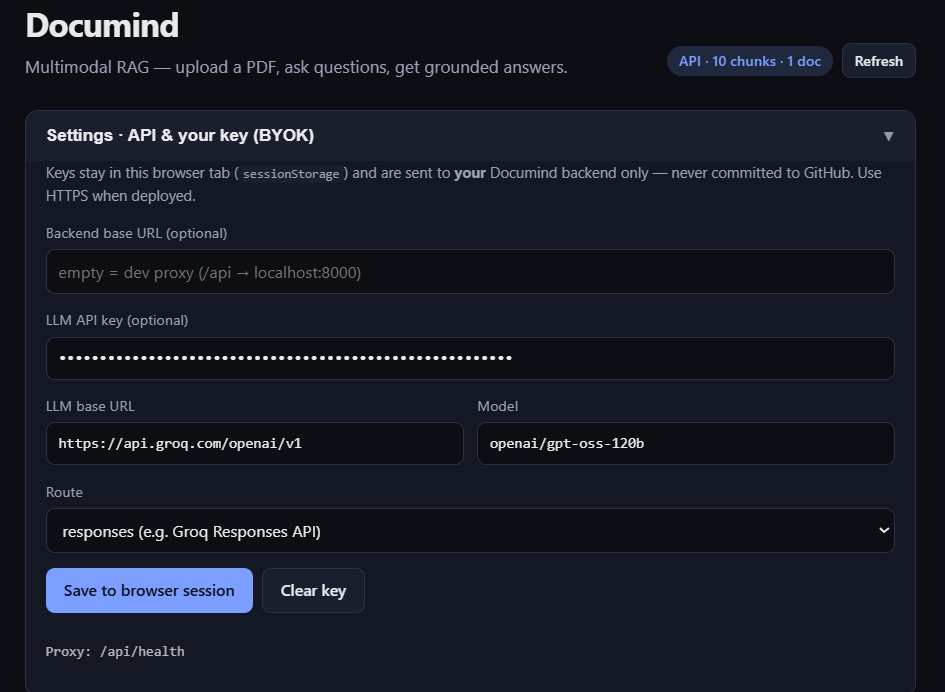
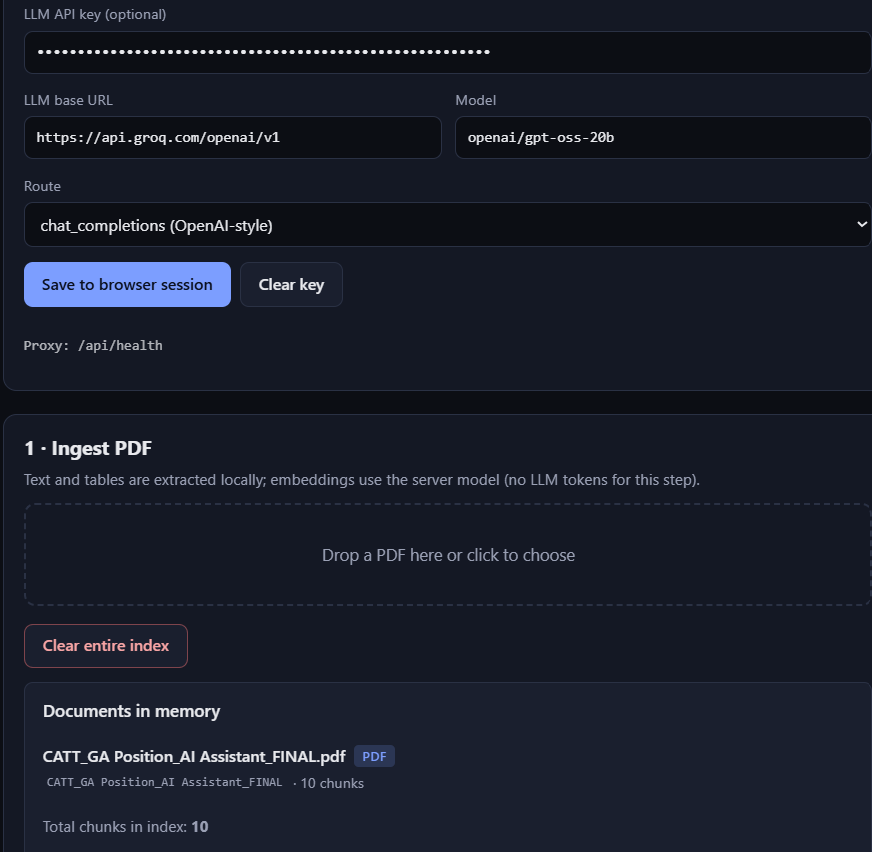
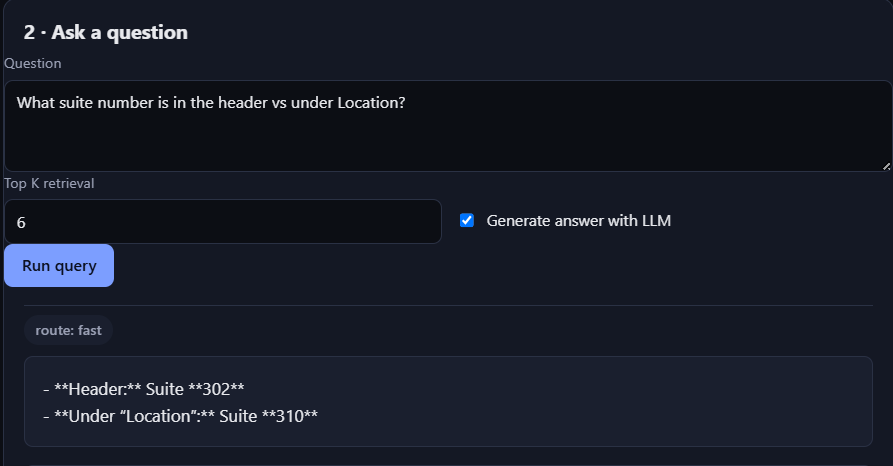
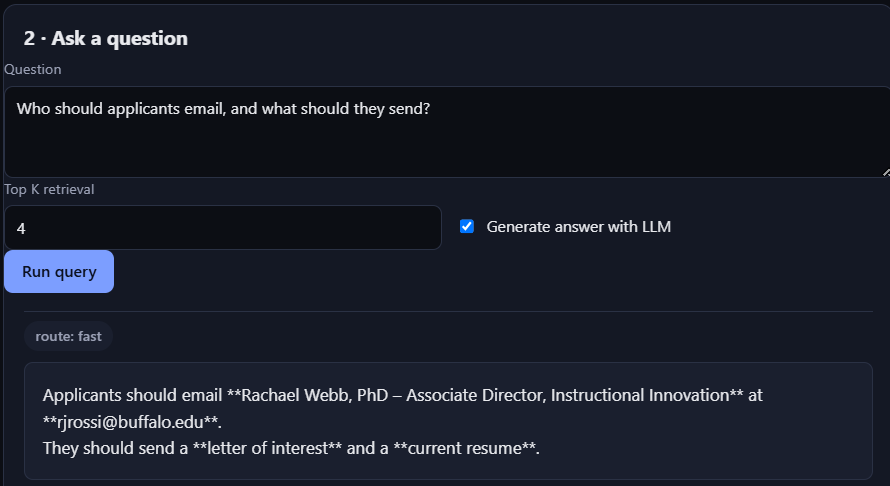
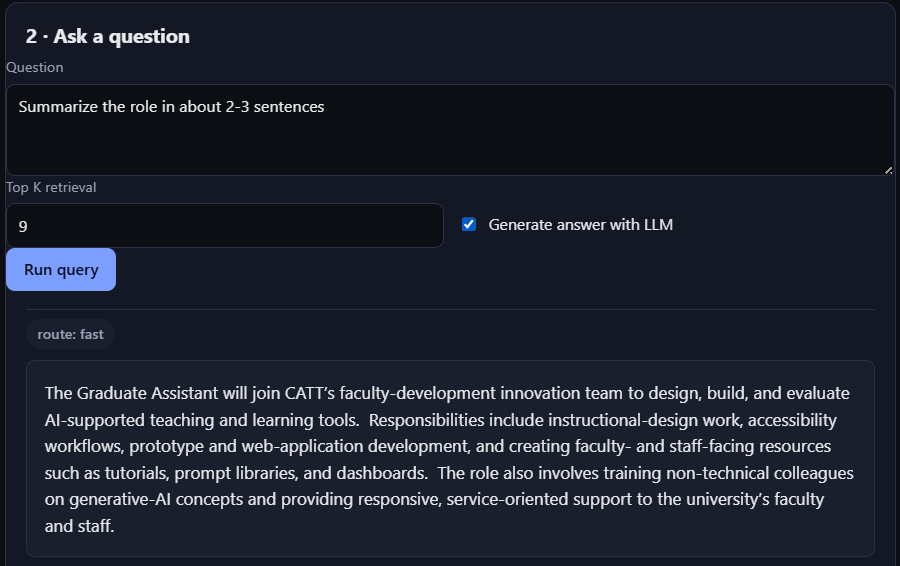
I gave DocuMind and a standard Gen-AI chatbot the same PDF (a graduate-assistant job posting) and asked both the same three questions. Pick one to replay DocuMind's real answer next to the chatbot's.
- Embed question
- Hybrid search
- Top-k chunks
- LLM answer
These are replays of real outputs from the experiment. Read the write-up in my LinkedIn post.
- Upload PDFDrop a file in the browser
- ExtractText and tables, plus OCR for scanned pages
- Chunk & embedsentence-transformers
- IndexFAISS (dense) + BM25 (keyword)
- AskPick your k for each question
- Hybrid retrievalCombines dense and keyword scores
- Top-k evidenceOnly these chunks reach the LLM
- Grounded answerAny OpenAI-compatible LLM, using your own key
Works with OpenAI, Groq or any compatible API. Keys stay in the visitor's browser session and are never stored.
Extraction runs locally and embeddings run on the server, so indexing a PDF costs nothing in LLM tokens.
A FastAPI backend with REST endpoints for ingestion and queries, a React UI, Docker with caching, deployed on Render and Vercel.
- 3 / 3answers matched a full-document chatbot
- 92%contextual grounding accuracy
- −50 msinference latency with caching
- −20%API cost
- FastAPI
- React
- FAISS + BM25
- sentence-transformers
- OCR
- Docker
- OpenAI / Groq (BYOK)